Dinkar Juyal
I am an ML Engineer at Meta, where I’m the tech lead for agent quality on Meta’s Business AI Agents — the feedback loops, evals, training data synthesis, and agentic harness work behind an agent now facilitating 10M+ conversations a week across 200M+ businesses. Previously, I was a Staff ML Researcher and Engineer at PathAI, focused on foundation models and computer vision for digital pathology.
My recent work is on credit assignment and evaluation for long-horizon agents: Self-Credit (dense supervision from sparse outcome rewards via intra-group rescaling), CDBench (controlled multi-fault debugging with RL and iterative repair), and ML-Dev-Bench (evaluating AI agents as ML engineers). Earlier work spans foundation models for pathology (PLUTO), domain generalization (ContriMix, best-performing official submission on the Camelyon17 WILDS leaderboard), and interpretability (Additive MIL), applied clinically in AI-based automation of enrollment criteria and endpoint assessment in liver disease trials (Nature Medicine, 2024). See publications for the full list.
I write about ML research — mostly notes on agents, foundation models, and evaluation. New posts go up on Substack first (see below); some are later mirrored here.
Talks & articles
- PyTorch Conference 2023 — Lightning talk on domain generalization in medical imaging
- ML Seminar Series, University of Minnesota — AI for digital pathology
ongoing projects
A few things I'm actively building and experimenting with:
writing on substack
Recent essays are published on Substack before anywhere else — that's where to find the newest posts.
latest posts
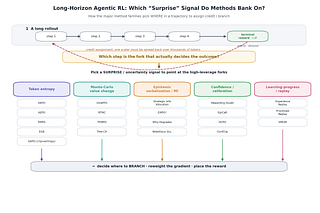
| Sep 19, 2026 | Where Does a Trajectory Actually Turn? |
|---|---|
| Aug 29, 2026 | Curiosity, Inspiration and Exploration |
| Jun 01, 2025 | How to think with images |
selected publications
-
Self-Credit: Credit Assignment for Long-Horizon Agentic RL via Intra-group RescalingarXiv preprint arXiv:2610.28388, 2026
-
CDBench: Controlled Multi-Fault Debugging with Reinforcement Learning and Iterative Repair2025
-
AI-based Automation of Enrollment Criteria and Endpoint Assessment in Clinical Trials in Liver DiseasesNature Medicine, 2024